 AI Compute Radar
The Tower Report · Week 44, 2026
Week 44, 2026 · 26 Oct – 1 Nov
Gemma 4 E4B is the pick; LFM2.5 8B-A1B gained the most
Compute weather
H100 at the Vast.ai median on 1 Nov: $2.85 per hour · the cheapest big cloud (AWS) listed 2.4× that · 20 price moves of 10 % or more · 5 popularity moves of 5 points or more. All prices
Name your graphics card or Mac once and every issue opens with what it runs this week. Choose your card
|
Pick of the week 8 billion on disk, under a gigabyte of context at 32KGemma 4 E4B · Google · Q4_K_M 4.6 GB Gemma 4 E4B by Google takes the eighth pick: Heat Score 59 to 76 between the readings of 24 and 30 October, the largest gain among models that run comfortably on a 24 GB card and are not on cooldown. Its Q4_K_M file measures 4.6 GB. At 8K context it needs 5.8 GB, it runs on the 8 GB cards and runs easily from 10 GB up; at 32K it needs 7.2 GB, and only 0.9 GB of that is context cache, a fifth of what last week's pick needs at the same length.
|
|
The pick on your card How Gemma 4 E4B's memory grows with context
The model accepts up to 131,072 tokens of context. Memory = measured weights + computed context cache + runtime, on an RTX 4090's 21.1 GB usable.
|
|
What to run this weekend The largest and the hottest model that fit each card class
"Runs" means our verdict for the measured Q4_K_M file at 8K context is "Runs easily" or "Runs". Largest = most parameters; hottest = highest popularity score. Check your own card |
|
Departures board Who gained and who lost this week
The score behind these moves is the one the board shows: a published composite of Hub trending, download growth, 30-day downloads and likes. On the pages it reads as popularity. The full board |
|
Price board What an hour cost last week
Week median = the median of the week's daily medians, glitch days excluded. "Few offers" marks a median over fewer than five offers. Cloud vs. market = cheapest big-cloud list price ÷ the same day's Vast.ai median. What these numbers are |
|
Chart of the week RTX 4090: fourteen days of hourly pricesThe RTX 4090 made the week's largest move on the price board, −36 % against the week before. 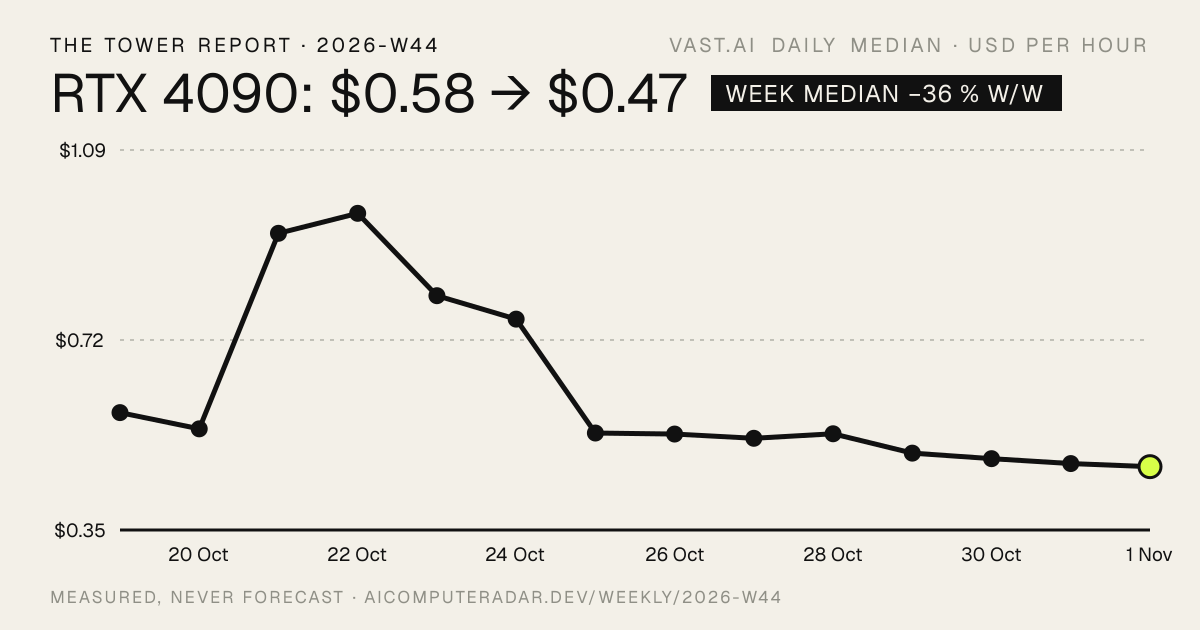
Daily median of Vast.ai's verified offers, UTC days, glitch days excluded by the same rule as the price board. Gaps are days without a reading. |
|
Price moves The week's largest day-over-day moves |
|
A number explained Five cards, five sources, no basketA reference price that settles contracts weighs five cards: H100 at 40 percent, B200 at 25, H200 at 15, A100 at 10 and RTX 4090 at 10. It publishes one number. This board publishes the five cards, source by source, and no number above them. On Sunday 1 November at 20:00 UTC one hour was listed at: H100 $2.59 posted at RunPod, $2.27 typical on the Vast marketplace across six offers, $3.29 at Lambda, $2.50 at Hyperstack, $6.88 at AWS. B200 $5.98 at RunPod, $8.75 on the Vast marketplace across six offers, $6.69 at Lambda, $6.00 at Hyperstack, $14.24 at AWS. H200 $3.59 at RunPod, $5.13 on the Vast marketplace across eight offers, $3.99 at Hyperstack, $7.91 at AWS; Lambda does not list it. A100 $1.19 at RunPod, $0.84 on the Vast marketplace across 41 offers, $1.99 at Lambda, $1.35 at Hyperstack, $2.74 at AWS. RTX 4090 $0.34 at RunPod and $0.47 on the Vast marketplace across 64 offers; no big cloud lists it. Read across a row and the spread is the story: for an H100 hour the cheapest and the dearest listing differ by a factor of three, for a B200 by 2.4, for an A100 by 3.3. A marketplace middle over six offers is a reading, not a market; a cloud's list price buys a whole instance with its own terms. Which of these a basket takes, and how a paid price differs from a listed one, is the difference between an index and a board. We do not make an index. Pick of the week 8 is Gemma 4 E4B: it grew in popularity faster than any other model that fits a 24 GB card and was not picked in the last four weeks. Its file measures 4.6 GB; 7 of its 42 layers cache the full context, so it needs 7.2 GB at 32K and runs easily on a 12 GB card. The week's board read: the RTX 4090 hour fell by a third against the week before, $0.50 against $0.76 as week middles on the Vast marketplace, and the H100 hour rose, $3.08 against $2.40, on six to eight offers. Every daily row behind these numbers is a CSV download, up to a year back, CC BY 4.0. |
|
What the pick costs Gemma 4 E4B, two ways, per dayFor 500,000 tokens a day over 4 active hours, the calculator's "regular" preset:
|
|
Newly measured Files measured this week, and where they fit
Memory from the measured GGUF file plus the computed context cache; "runs" means our verdict is "Runs easily" or "Runs". Check your own card |
|
Rent or buy, one number 3,263 rented hoursAt last week's Vast.ai median of $0.49 an hour, the RTX 4090's launch list price of $1,599 (NVIDIA launch MSRP, Oct 2022) equals 3,263 rented hours, ≈ 8 years at 8 h/week. Electricity and resale value are left out on both sides.
|
|
Class of the week L40SLast week's Vast.ai median: $0.80 an hour. Since we started reading it 28 days ago: 0 %. Cheapest source at the week's end: RunPod at $0.79 (list price). The cheapest big cloud, AWS, listed 2.3× the marketplace median. 30 of 48 tracked open models run comfortably on one at 8K context; the largest comfortable one is Qwen AgentWorld 35B-A3B.
|
|
Maker board Which labs hold the top-10 slots
Counted from the popularity ranking when this issue was built, Monday 05:45 UTC; the 7-day change is the mean per-model change. The full board |
|
New on the radar Added this week
|
|
From the tower What changed on the site
|
|
From the methodology desk What this issue does not sayPrices above were read on Sunday 1 November 2026 at 20:00 UTC; marketplace figures are the middle of the offers listed then, with the offer count, and cloud figures are list prices for one GPU. Six or eight offers behind an H100 or B200 middle make it a reading, not a market. The index weights are stated as a fact about a third party's method; we neither publish that index nor link to products built on it. The two models added to the catalog this week, LFM2.5 24B-A2B and Ornith 1.5 122B, have no popularity reading before 4 November. No forecast. |
Forward this to someone with a graphics card. They can subscribe at aicomputeradar.dev/newsletter. Replies reach a person.
The Tower Report · every Monday
Monday's board, in your inbox.
Prices, the pick, what newly fits your card. Measured, never forecast. One mail a week, one click to leave.
Name your card and every issue opens with what it runs this week. You can change it by subscribing again with the same address.
Double opt-in; you confirm by one click. Details in the privacy policy · what is in an issue